
An AI detector estimates whether writing shows patterns associated with AI-generated text. A plagiarism checker identifies overlap with existing sources. The AI detector vs plagiarism checker distinction matters because these tools answer different questions: possible AI involvement is not the same as source copying, and neither result automatically establishes misconduct. Scribbr’s explanation of the two checks makes this difference explicit.
To choose the right check, start with the concern you need to investigate—not the percentage you hope to receive.
Last reviewed: October 29, 2026.
What each check can tell you
| What to compare | AI detector | Plagiarism checker |
|---|---|---|
| Primary question | Does this writing resemble text the system associates with AI generation? | Does this wording overlap with material the service can search? |
| Basis for the result | Patterns learned or assessed by a detection model. | Comparison with available websites, publications, or document repositories. |
| Typical report | A classification, confidence estimate, or percentage of text flagged, depending on the product. | A similarity score with matching passages and source details. |
| Useful follow-up | Review the writing process and applicable AI-use policy. | Compare the passages, quotations, paraphrases, and citations. |
| What it cannot establish alone | Who wrote the document or whether any AI assistance was prohibited. | Whether a match constitutes plagiarism or unmatched writing is original. |
The distinction is visible in the documentation for GPTZero’s classifications and Turnitin’s source-matching reports. A single service can offer both functions, but that does not make the resulting scores interchangeable.
A similarity report is not a plagiarism verdict
A plagiarism checker is more accurately understood as a source-comparison tool. For example, Turnitin compares submissions with material that includes web content, publications, and previously submitted papers. Its similarity score summarizes matching text; the report helps a reviewer locate and examine those matches.
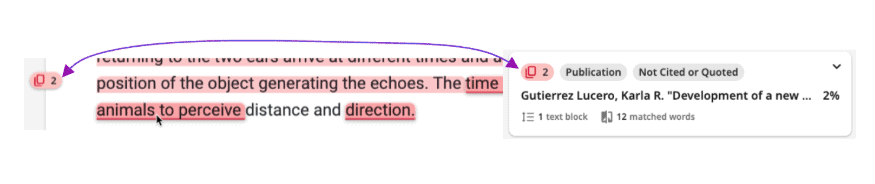
A match can be legitimate. A properly attributed quotation, a reference entry, or common wording may appear in a report without representing misconduct. Turnitin explicitly states that it does not determine whether plagiarism occurred. The reviewer must assess how the source was used.
There is also no universal safe similarity percentage. A substantial amount of correctly quoted material can require a different judgment from one short, unattributed passage containing a central argument. Follow the assignment’s requirements, but do not mistake a numerical threshold for a complete evaluation of attribution.
A low result is not a certificate of originality, either. The checker cannot establish what happened with sources outside its comparison coverage. Turnitin’s student guidance also notes that a displayed 0% can sometimes reflect rounding rather than an absolute absence of matches.
More importantly, plagiarism is not limited to identical sentences. The Harvard Guide to Using Sources explains that borrowed ideas and paraphrases also require appropriate acknowledgment. Rewording a source does not remove the obligation to credit it. That is why reading the sources remains necessary even when a report finds little matching text.
An AI detection score depends on what the product measures
AI detectors analyze the submitted writing rather than simply searching for a duplicate passage. GPTZero describes training its model on human-written and AI-generated text. A classification produced from those patterns is an inference about the text—not a recovered chat transcript or a record of the author’s drafting process.
The most important step before interpreting an AI percentage is to read its definition. Two products can display percentages while measuring different things.
Turnitin: a share of qualifying text
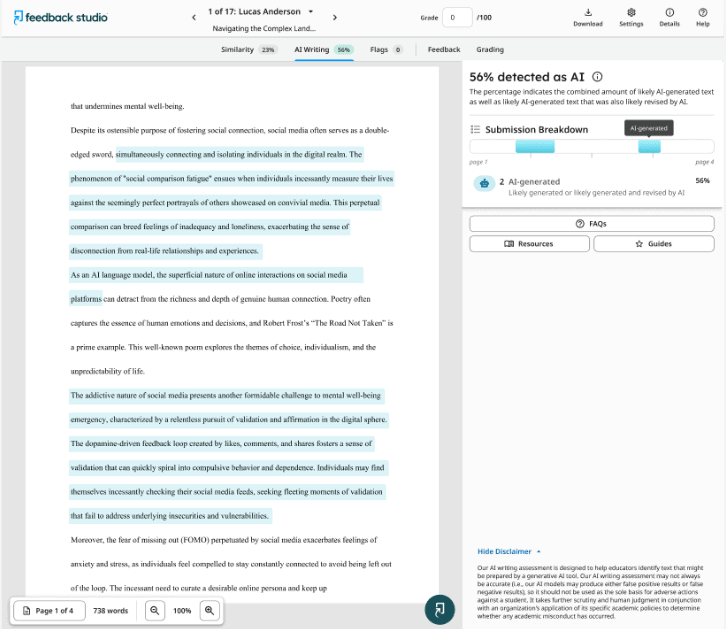
According to Turnitin’s AI Writing Report documentation, its overall percentage represents qualifying text that the system identifies as potentially AI-generated, including certain AI-generated text subsequently modified with AI tools. “Qualifying text” refers to prose sentences in long-form writing. The percentage is not the probability that a student broke a rule, and its denominator is not necessarily every element of the uploaded document.
GPTZero: confidence in a classification
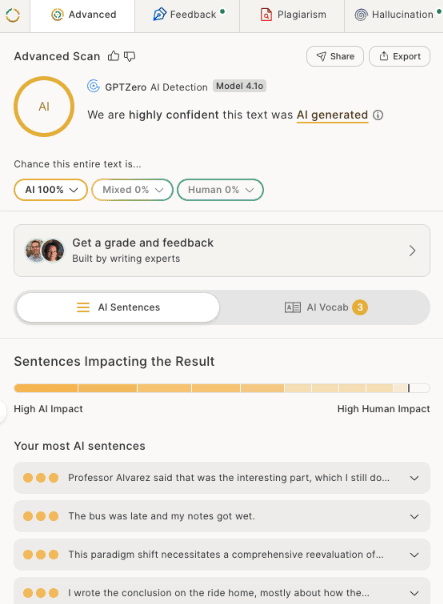
GPTZero defines its percentage differently: it expresses the model’s confidence in a classification of the text as AI, mixed, or human. It does not represent the percentage of sentences written by AI. Treating that confidence estimate as a measured share of AI-written content would misread the report.
Do not average different tools’ scores or combine an AI score with a similarity score. The underlying measurements are different, so the resulting number would not have a validated interpretation. Likewise, a model’s classification confidence should not be treated as a calibrated probability of academic misconduct.
Why low similarity and a high AI score can appear together
Different results are not necessarily contradictory. Turnitin states that its AI-writing percentage and similarity score are independent measurements. The following hypothetical situations illustrate the distinction; they are not results from tests conducted for this article.
An AI-generated draft has few source matches. Suppose the generated wording does not closely match the checker’s comparison material. A similarity report may show little overlap while an AI detector flags writing patterns. The lack of matches would answer the source-overlap question, not establish human authorship.
A human-written essay contains a copied paragraph. A writer independently drafts most of an essay but inserts an unattributed passage from an indexed article. Source comparison could reveal the passage even if an AI detector classifies the document as human. Human authorship does not resolve the attribution problem.
A research paper includes legitimate quotations. A writer accurately quotes and cites several passages. Those passages may produce matches, but the appropriate response is to review their attribution and relevance—not automatically accuse the writer or remove necessary citations to lower the score.
Both results are low, but a policy issue remains. Imagine an assignment prohibits AI-generated drafting, yet the writer uses it and neither check identifies a concern. The reports would not change the assignment’s requirements. A tool’s failure to flag something does not establish that the writing process followed the rules.
Is AI-generated writing automatically plagiarism?
No single detector result can settle that question. Keep three issues separate: how sources were used, what assistance contributed to the writing, and whether that assistance was allowed. Human-written and AI-generated documents can both contain unattributed source material; permitted AI assistance is a different issue from prohibited use.
For a concrete institutional example, Princeton’s guidance on generative AI tells students to establish what their course permits and disclose allowed use. It explains that expectations can differ between courses and assignments. Those are Princeton’s requirements, not a universal policy for every school or publisher.
Before using AI, check the applicable instructions. Disclosure does not turn prohibited assistance into permitted assistance. For editorial or client work, obtain a clear answer about allowed uses rather than assuming that a low detector score fulfills the brief.
How reliable are the results?
“Accuracy” is not directly comparable across these categories. Finding matching wording and estimating possible AI generation are different tasks. A meaningful evaluation must specify what was tested and what counted as a correct result.
AI detectors can make errors in both directions
A false positive occurs when human-written text is classified as AI-generated. A false negative occurs when AI-generated text is classified as human. GPTZero acknowledges both possibilities and notes that its performance varies with text length, similarity to its training material, and substantial modification after generation.
Document suitability matters, too. Turnitin’s report requirements and limitations specify at least 300 words of long-form prose and warn that the model does not reliably assess formats such as poetry, scripts, or code. Do not generalize a product’s prose-writing claims to every kind of content.
Independent findings also need context. A study published in June 2026 evaluated four detectors using 160 English-language academic documents, with the experimental AI text generated in May 2025. Performance differed across tools and document categories, including mixed and modified writing. The authors emphasized that their findings represented a particular testing snapshot. An October 2026 correction clarified the generative model used without changing the analyses or conclusions.
Fairness findings require the same care. A 2023 study of seven detectors found frequent misclassification of non-native English writers’ TOEFL essays. That is important evidence about those tested systems and texts, not proof that every subsequent detector version has the same error rate.
When evaluating an accuracy claim, ask whether the test included writing like yours, identified the tested versions, and reported false positives separately from successful AI detection. A headline percentage without that context is not enough to guide a consequential decision.
Similarity checkers have a different blind spot
Their usefulness depends on comparison coverage and report settings. Turnitin’s assignment settings, for example, allow choices about comparison repositories and exclusions for quotations, bibliographies, and small matches. Check those settings before comparing two reports. A correctly identified quotation is a real match—not necessarily a false accusation or a technical error.
Which check should you use?
For source use and attribution, prioritize source comparison. A similarity report can help you locate passages to inspect. Then check whether quotations are marked, paraphrases accurately represent the source, and borrowed ideas are credited. The goal is defensible attribution, not the lowest possible number.
For concerns about AI assistance, start with the policy and writing process. Determine what assistance was allowed and what evidence is relevant. Do not assume that buying access to an AI detector makes it appropriate for an institutional investigation. Cornell’s teaching guidance, for example, advises against using automatic detection algorithms to establish generative-AI academic integrity violations.
Use both only when you need both kinds of information. A source-attribution review does not automatically require an AI assessment. Conversely, an AI report does not replace checking citations. For manuscripts, client documents, and classroom work, choose an approved process that matches the actual concern and the consequences of getting it wrong.
What to do when a report flags your writing
Investigate the specific concern rather than repeatedly rescanning until a preferred result appears. Use this review sequence:
- Identify the report and the rule. Confirm whether the concern involves source matching, possible AI generation, or both. Obtain the relevant assignment, publication, or workplace requirements.
- Read the flagged passages. Request the report rather than relying on a screenshot of its headline score. For similarity matches, compare the actual wording and source context.
- Check attribution carefully. Review quotation marks, citations, and paraphrases. Correct a genuine sourcing problem because the attribution needs correction—not simply to make a highlighted passage disappear.
- Gather relevant process evidence. Preserve existing outlines, source notes, drafts, revision history, and any required AI-use disclosure. Explain how the argument and wording developed.
- Ask for an appropriate human review. Discuss the specific passages and evidence with the instructor, editor, or designated reviewer. Follow the applicable review or appeal process when a result is disputed.
This approach draws on Harvard’s source-attribution guidance and UCLA’s emphasis on drafts, notes, version history, and discussion. Process records can inform an assessment, but no single record should be treated as infallible proof. Likewise, missing version history does not by itself prove misconduct.
For reviewers, give the writer a meaningful opportunity to explain their work. For writers, avoid changing accurate language solely to satisfy a detector or using a “humanizer” to conceal prohibited assistance. Address the underlying writing or policy issue instead.
Check document privacy before uploading
Before submitting student work, an unpublished manuscript, or a confidential client document, establish whether you are authorized to share it with that service. Vanderbilt’s academic integrity guidance warns about third-party detection services with unclear privacy and data-use practices.
Read the provider’s actual policies and account settings. Check how long submissions are retained, whether they may be used for model training, whether they enter a comparison repository, who can access them, and how deletion works. Do not assume that “free,” “private,” or “no repository” answers all those questions.
For example, Turnitin distinguishes repository options that can make submissions available for future comparison from an option that excludes them from comparison repositories. That setting addresses repository use; it should not be interpreted as a blanket statement about every aspect of processing or retention.
When permission or handling terms are unclear, use an institutionally approved route or resolve the uncertainty before uploading. More scans are not automatically worth wider distribution of a sensitive document.
Choose the evidence you need—not a passing score
Before running a check, write down the question you need answered: a possible source match, an attribution problem, or a concern about permitted assistance. Then choose the report and review process that address that question. The useful outcome is an explanation supported by passages, sources, and writing context—not a reassuring percentage with no clear meaning.